Lumen Search
Open source · Hybrid document search (RAG)
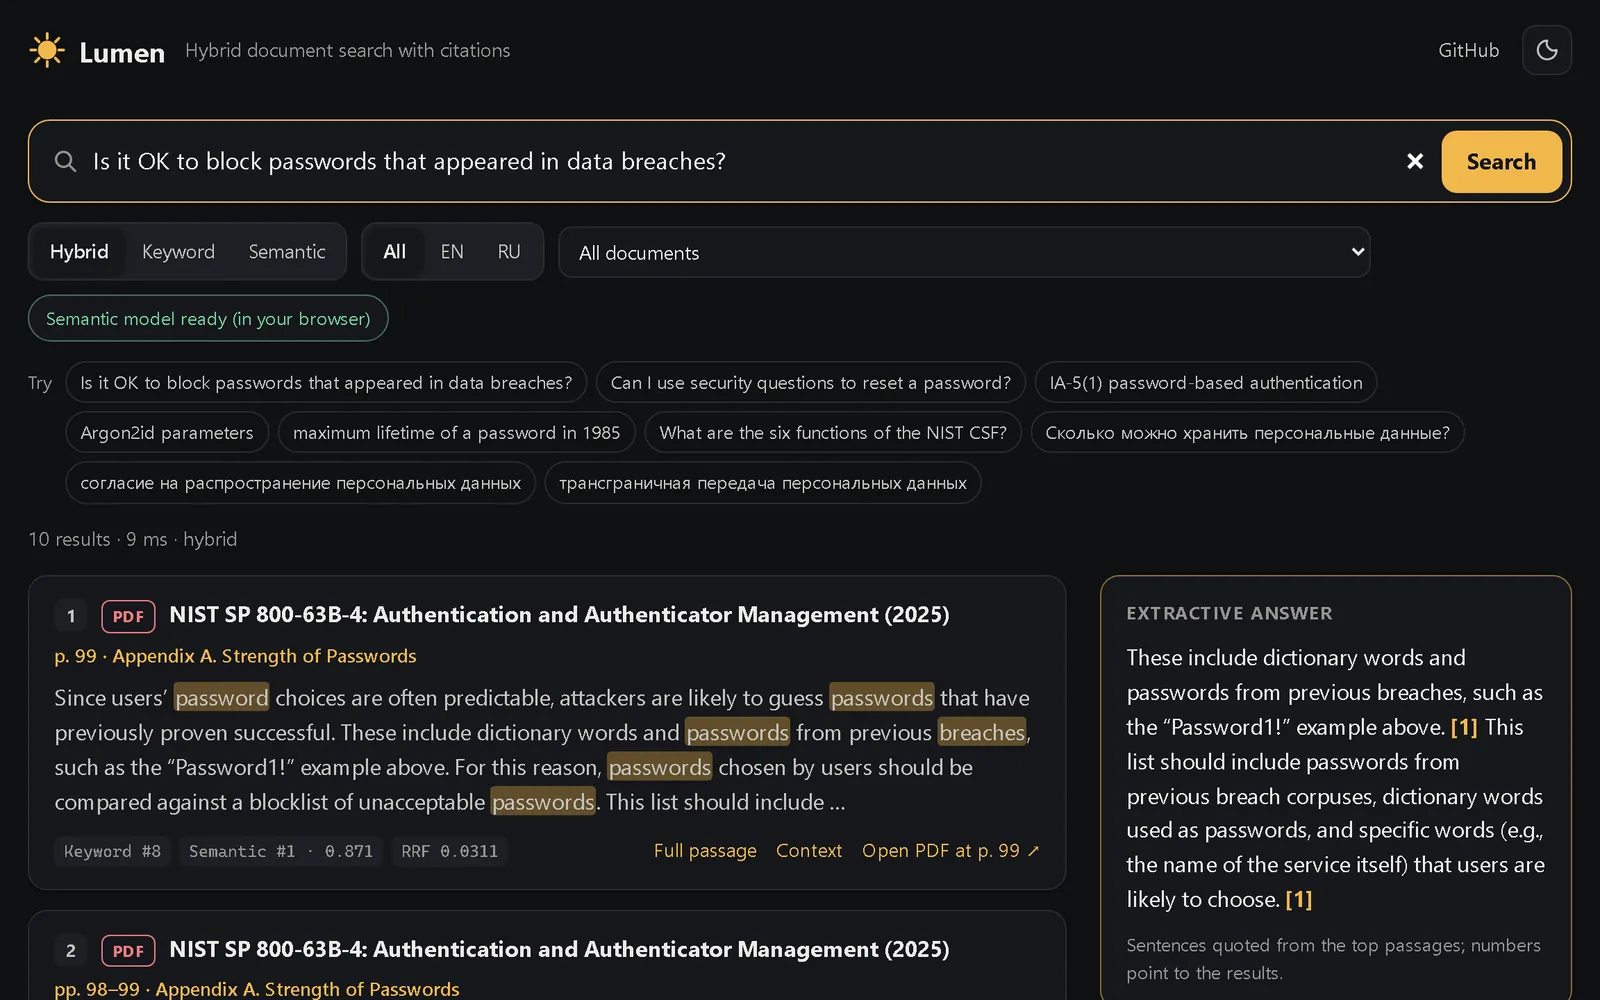
Hybrid document search with citations over PDF, Word, Excel and scanned pages, in English and Russian — BM25 plus multilingual embeddings in FAISS, OCR and a FastAPI service.
Problem
Documents arrive as a mix of PDFs, Word files, spreadsheets and scans; plain keyword search misses paraphrases and can't say where an answer came from.
Solution
Structure-aware parsing with OCR, BM25 and embedding retrieval fused by rank, optional reranking, and citations down to the page, article or spreadsheet row.
Built in
83.9% of 62 labelled questions get a correct passage in the top five after reranking. Live demo in the browser; tests on three Python versions and a Docker smoke test in CI.
Overview
Lumen Search is the open-source counterpart of the system I build at work: one search over PDFs, Word files, Excel sheets and scans, where every answer shows exactly where it came from. It indexes eight public documents — NIST and OWASP security guidance in English, the Russian personal data law in Russian, and two scans that only OCR can read.
Parsing follows each document's structure — PDF bookmarks and numbered headings, Word heading styles, one spreadsheet row per record — so results cite a page and section, an article of a law, or a sheet and row. Retrieval runs BM25 over Snowball-stemmed English and Russian words next to multilingual-e5 embeddings in FAISS, fuses the two rankings, and can rerank the top results with a multilingual cross-encoder.
Quality is measured on 62 hand-labelled questions: hybrid search puts a correct passage in the top five for 75.8% of them, and reranking raises that to 83.9%; the README also says where it is weak. The service starts with one docker compose command, and the live demo runs the same search in the browser with a 66 MB int8 model, while CI checks the JavaScript port against the Python code.
What it does
- Parses PDF, Word, Excel, Markdown and HTML; scanned pages go through Tesseract OCR in English and Russian
- Chunks by section and spreadsheet row, so every result cites a page, a law article or a row
- Hybrid retrieval: BM25 and multilingual-e5 embeddings in FAISS, fused by rank, with optional cross-encoder reranking
- FastAPI service with a Redis cache, answers with numbered sources, and a demo that runs in the browser
What's next
Hiring for a full-stack, Python or AI role — or need something like this built? Let's talk.
I'm available immediately — on-site or hybrid in Moscow, or remote; full-time or contract. I reply within 48 hours — faster on Telegram.